Stable Diffusion 2
zm_config.json + model.weights.h5 +
tokenizer.json). Load with from_weights("zeromodels/<variant>").
Stable Diffusion 2.x, ported to pure Keras 3: the Stable Diffusion
latent-diffusion architecture with the second-generation conditioning. It reuses the
SD 1.x family end to end (StableDiffusion2Model is StableDiffusionModel,
StableDiffusion2TextToImage is StableDiffusionTextToImage, each with the SD 2
configuration), so everything on that page applies: one container per repo, generate
from BaseDiffusion, the schedulers, both data formats. What changes is the config:
- Text encoder: OpenCLIP ViT-H/14's text tower, 1024 wide, 16 heads,
gelu, shipped truncated to its 23rd (penultimate) layer, which SD 2 conditions on. - UNet: 1024-d cross-attention, one head count per level (
(5, 10, 20, 20), a 64-wide head everywhere, where SD 1.x used 8 heads at every level) and a linear token projection in the Transformer2D blocks instead of the 1x1 conv. - Tokenizer: the same CLIP BPE, padded with
!(id 0) the OpenCLIP way rather than<|endoftext|>, so the empty prompt used for classifier-free guidance is[<|startoftext|>, <|endoftext|>, !, !, ...]. - 768px checkpoints (
stable-diffusion-2,stable-diffusion-2-1): built at a 96x96 latent and trained with the v-prediction objective; their repos carry a v-prediction DDIM scheduler, whichgeneratepicks up fromscheduler_config. - SD-Turbo (
sd-turbo): SD 2.1 distilled with Adversarial Diffusion Distillation to generate in 1 to 4 steps without guidance; its repo carries an Euler scheduler withtrailingtimestep spacing andgenerate_argsof 1 step,guidance_scale=0.0.
The weights are converted once, offline, and hosted: on-the-fly hf: conversion is
deliberately not supported for diffusion models. The original stabilityai/* repos are
no longer on the Hub; the conversion sources are the sd2-community mirrors.
Links:
- Paper: High-Resolution Image Synthesis with Latent Diffusion Models (arXiv:2112.10752)
- Reference implementation: diffusers
StableDiffusionPipeline - License: CreativeML Open RAIL++-M
See also stable_diffusion.md, clip.md.
Variants
Preconverted, float32 weights are hosted under zeromodels/. Load with
from_weights("zeromodels/<variant>"). Each repo is one container: UNet (866M) + VAE
(84M) + OpenCLIP text encoder (340M), 1.29B parameters, 5.16 GB (4.81 GiB, one
model.weights.h5). The SD 2 checkpoints are released under the CreativeML Open RAIL++-M
license; SD-Turbo under the Stability AI Non-Commercial Research Community License.
| Variant | Hub | Resolution | Objective | Training |
|---|---|---|---|---|
stable-diffusion-2-base |
zeromodels/stable-diffusion-2-base |
512 | epsilon | from scratch: 550k steps at 256px on LAION-5B (aesthetics >= 4.5), then 850k steps at 512px |
stable-diffusion-2 |
zeromodels/stable-diffusion-2 |
768 | v-prediction | 2-base + 150k steps at 768px |
stable-diffusion-2-1-base |
zeromodels/stable-diffusion-2-1-base |
512 | epsilon | 2-base + 220k steps at 512px (punsafe 0.98) |
stable-diffusion-2-1 |
zeromodels/stable-diffusion-2-1 |
768 | v-prediction | 2 + 55k steps (punsafe 0.1) + 155k steps (punsafe 0.98) at 768px |
sd-turbo |
zeromodels/sd-turbo |
512 | epsilon, 1 to 4 steps, no guidance | SD 2.1 distilled with Adversarial Diffusion Distillation (non-commercial) |
Use the -base checkpoints for 512px images and the others for 768px; each repo's
zm_config.json builds the graph at its native size.
API
Configs are typed: StableDiffusion2Config (composite, model_type
"stable_diffusion_2") over StableDiffusion2UNetConfig (a UNet2DConditionConfig
with the SD 2 widths), AutoencoderKLConfig and StableDiffusion2TextConfig (a
CLIPTextConfig with the ViT-H/14 sizes), plus the scheduler config and the token ids
(pad_token_id 0). Flat constructor, unet_ / vae_ / text_ prefixes, like SD 1.x.
StableDiffusion2TextToImage
StableDiffusionTextToImage with the SD 2 configuration; generate is unchanged:
generate(
    input_ids,
    attention_mask=None,
    negative_input_ids=None,
    num_inference_steps=None,
    guidance_scale=None,
    seed=None,
    latents=None,
)
Returns (batch, H, W, 3) uint8 images at the checkpoint's resolution; latents is
(batch, 64, 64, 4) for the 512px checkpoints and (batch, 96, 96, 4) for the 768px
ones (channels_first: channels second). Defaults come from the repo's generate_args
(50 steps, guidance 7.5). See Stable Diffusion
for the argument table.
StableDiffusion2Model
The container, StableDiffusionModel with the SD 2 configuration: the same three
disconnected paths (.unet, .vae, .text_encoder) and the same inputs / outputs, with
encoder_hidden_states 1024 wide. It loads the same repo as the task class.
The components are the SD 1.x classes, UNet2DConditionModel (built with
num_attention_heads=(5, 10, 20, 20), use_linear_projection=True,
cross_attention_dim=1024) and AutoencoderKL; see their tables on the
Stable Diffusion page.
Preprocessing
StableDiffusion2Tokenizer
StableDiffusionTokenizer with ! as the pad token: CLIP BPE, <|startoftext|> /
<|endoftext|> framing, truncated and !-padded to 77 tokens. Returns
{"input_ids", "attention_mask"}.
End-to-end example
import os

os.environ["KERAS_BACKEND"] = "torch"  # or "jax" / "tensorflow"

from PIL import Image
from zeromodels.models.stable_diffusion_2 import (
    StableDiffusion2TextToImage,
    StableDiffusion2Tokenizer,
)

model = StableDiffusion2TextToImage.from_weights("zeromodels/stable-diffusion-2-1-base")
tokenizer = StableDiffusion2Tokenizer.from_weights(
    "zeromodels/stable-diffusion-2-1-base"
)

inputs = tokenizer(
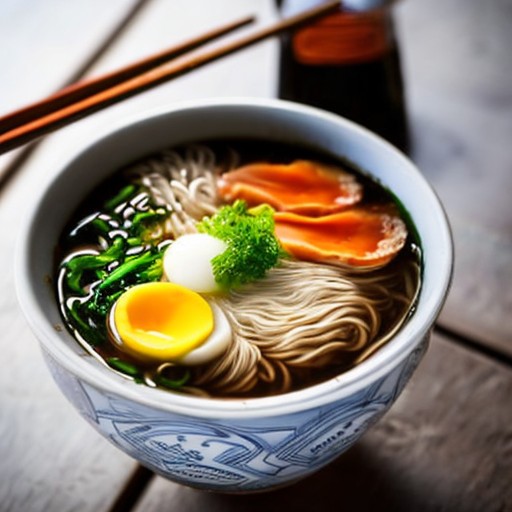
    "a steaming bowl of ramen on a wooden table, food photography, shallow depth of field"
)
images = model.generate(**inputs, num_inference_steps=50, guidance_scale=7.5, seed=2)

Image.fromarray(images[0]).save("ramen.png")  # (512, 512, 3) uint8
768px, v-prediction
The 768px checkpoints need no extra arguments; the v-prediction DDIM scheduler and the 96x96 latent come from the repo:
model = StableDiffusion2TextToImage.from_weights("zeromodels/stable-diffusion-2-1")
tokenizer = StableDiffusion2Tokenizer.from_weights("zeromodels/stable-diffusion-2-1")
images = model.generate(
    **tokenizer("a lighthouse on a cliff at dusk, oil painting")
)  # (1, 768, 768, 3)
SD-Turbo
One step, no guidance (the repo's defaults; up to 4 steps sharpen a little):
model = StableDiffusion2TextToImage.from_weights("zeromodels/sd-turbo")
tokenizer = StableDiffusion2Tokenizer.from_weights("zeromodels/sd-turbo")
images = model.generate(
    **tokenizer(
        "a cinematic shot of a baby raccoon wearing an intricate italian priest robe"
    )
)
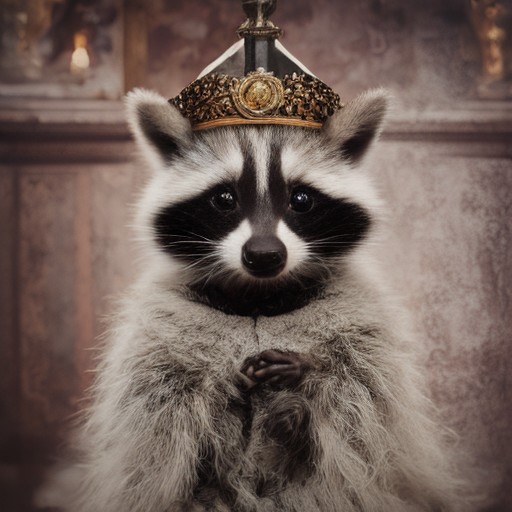
The same prompt and latent through diffusers' StableDiffusionPipeline (fp32) match to
1 uint8 level: 99.9% of pixels identical at 1 step (PSNR 82 dB), 99.8% at 4 steps.
Negative prompts, batching, explicit latents for cross-backend reproducibility, other
resolutions and the container-only use work exactly as on the
Stable Diffusion page. Image-to-image
(generate(..., image=..., strength=...)) works as described for
BaseDiffusion.
Verified against diffusers
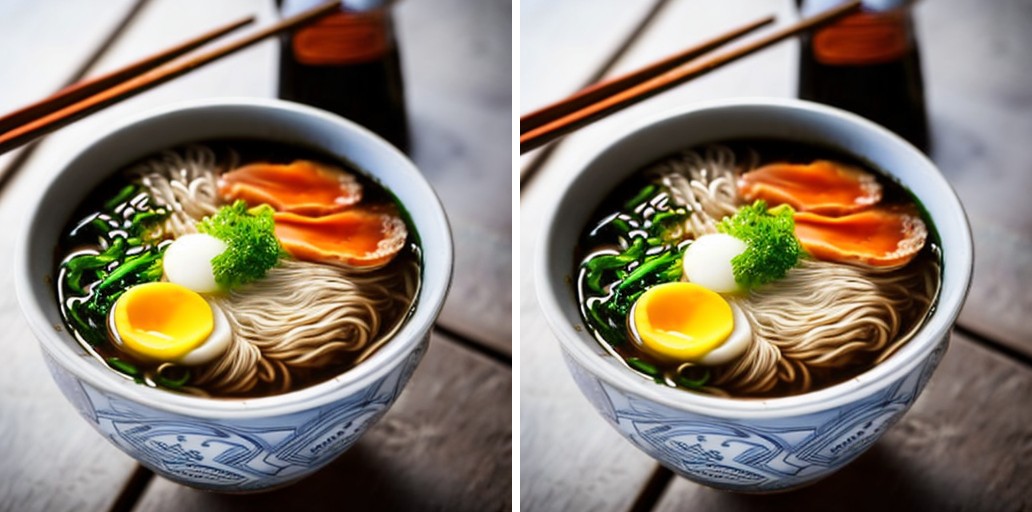
The ramen prompt above with the same initial latent, PNDM 50 steps and guidance 7.5
through StableDiffusion2TextToImage (left) and diffusers' StableDiffusionPipeline
(right) on stable-diffusion-2-1-base, both fp32:
tokenizer input_ids           identical
text_encoder                  max|d|=1.5e-05
unet noise_pred (t=981)       max|d|=7.2e-07
vae decode                    max|d|=2.6e-06
final image (uint8)           max|d|=1  mean|d|=0.0095  PSNR=68.3 dB  identical_pixels=97.22%
The 768px v-prediction checkpoint (stable-diffusion-2-1, DDIM 20 steps, same latent)
matches the same way: UNet 8.3e-6, VAE 7.9e-5, final image max 1 uint8 level, 99.3% of
pixels identical, PSNR 74.6 dB.
Data Format
Both channels_last and channels_first are supported, as for
Stable Diffusion; generate always returns
(batch, H, W, 3) uint8.
Memory and speed
The fp32 container is 5.16 GB. At 512px a guided batch-1 run needs a little over 7 GB of GPU memory in eager Torch (about 1.5x diffusers' eager time); at 768px the self-attention runs over 9216 tokens, so the guided run needs roughly 12 GB, or the CPU.
Loading Fine-tuned Weights
Any repo laid out like the hosted ones (zm_config.json declaring
StableDiffusion2Model, the weights, tokenizer.json) loads with
from_weights("<org>/<repo>"). The hf: prefix raises for diffusion models: convert a
diffusers-format SD 2 checkpoint once with
zeromodels/models/stable_diffusion_2/convert_stable_diffusion_2_diffusers_to_keras.py
(transfer_stable_diffusion_2(repo), pip install zeromodels[conversion]) and host the result.