Stable Diffusion 3
zm_config.json + the float16 weights +
tokenizer.json / tokenizer_3.json). Load with
from_weights("zeromodels/<variant>").
Stable Diffusion 3, ported to pure Keras 3: a rectified-flow model whose denoiser is the
MMDiT, a multimodal diffusion transformer in which the latent tokens and the text tokens
attend to each other jointly, conditioned on the timestep and the pooled text embeddings
through adaptive layer norms. It keeps the SD family's shape (one container per repo,
generate from BaseDiffusion, the schedulers, both data formats) with new parts:
- MMDiT (
SD3Transformer2DModel): the 16-channel latent is patchified (2x2) into 1536-d tokens with a sinusoidal position table cropped from a 192x192 grid; 24 joint blocks of 24 heads, each with AdaLN-Zero modulation of both streams, joint attention over the concatenated latent + text tokens, and gated GELU feed-forwards; a final adaptive norm and projection unpatchify the velocity. 2B parameters. - Three text encoders: CLIP ViT-L/14 (768-d) and OpenCLIP ViT-bigG/14 (1280-d), each with a projection, and T5-XXL (4.7B, 4096-d, 256 tokens). The two CLIP penultimate states are concatenated (2048-d), zero-padded to 4096 and followed along the sequence by the T5 states (77 + 256 tokens); the projected pooled CLIP states (2048-d) feed the conditioning embedding.
- T5 is optional and separate: the container holds the MMDiT, the VAE and the two CLIP
towers (2.9B, 5.8 GB float16); the T5-XXL encoder is hosted once for every SD 3 / 3.5
checkpoint (
zeromodels/t5-v1_1-xxl-encoder, anSD3T5EncoderModel, 9.5 GB float16) and attached withtext_encoder_3=. Without it the T5 features are zeros, SD 3's documented memory-saving mode (prompt adherence drops, the images stay good). - VAE: 16 latent channels, no quant convolutions,
scaling_factor1.5305 andshift_factor0.0609 (z = (x - shift) * scale), built in float32 (force_upcast). - Sampler:
FlowMatchEulerDiscreteSchedulerwithshift3.0 (rectified flow: the timesteps aresigma * 1000, a step isx + (sigma_next - sigma) * v); 28 steps at guidance 7.0 by default. No negative prompt means the encoded empty prompt. - One tokenizer call:
StableDiffusion3Tokenizerruns the CLIP BPE (the second tower's!-padded ids are derived from the mask, as SDXL) and the T5 SentencePiece tokenizer, returning{"input_ids", "attention_mask", "input_ids_3"}. - float16 weights, the release precision;
from_weightsbuilds the model in float16 by default (load_dtype="float32"for float32).
The weights are converted once, offline, and hosted: on-the-fly hf: conversion is
deliberately not supported for diffusion models. The upstream repo is gated behind the
Stability AI Non-Commercial Research Community License.
Links:
- Paper: Scaling Rectified Flow Transformers for High-Resolution Image Synthesis (arXiv:2403.03206)
- Reference implementation: diffusers
StableDiffusion3Pipeline - License: Stability AI Non-Commercial Research Community License
See also stable_diffusion_3_5.md, stable_diffusion_xl.md, clip.md.
Variants
| Variant | Hub | Resolution | Sampler | License |
|---|---|---|---|---|
stable-diffusion-3-medium |
zeromodels/stable-diffusion-3-medium |
1024 | flow-match Euler (shift 3), 28 steps, guidance 7.0 | Stability AI Non-Commercial Research Community |
t5-v1_1-xxl-encoder |
zeromodels/t5-v1_1-xxl-encoder |
text encoder (shared with SD 3.5) | Apache 2.0 (Google T5 v1.1) |
API
Configs are typed: StableDiffusion3Config (composite, model_type "stable_diffusion_3")
over StableDiffusion3TransformerConfig, StableDiffusion3VAEConfig,
StableDiffusion3TextConfig (CLIP ViT-L/14 with its 768-d projection) and
StableDiffusionXLTextConfig2 (OpenCLIP ViT-bigG/14 with its 1280-d projection), plus
the scheduler config, the CLIP and T5 token ids and max_sequence_length (256). Flat
constructor with transformer_ / vae_ / text_ / text_2_ prefixes.
StableDiffusion3TextToImage
StableDiffusionTextToImage's generate over the SD 3 graph:
generate(
    input_ids,
    attention_mask=None,
    negative_input_ids=None,
    num_inference_steps=None,
    guidance_scale=None,
    seed=None,
    latents=None,
    image=None,
    strength=None,
    denoising_start=None,
    denoising_end=None,
    output_type="image",
    input_ids_3=None,
    negative_input_ids_3=None,
)
| Argument | Description |
|---|---|
input_ids, attention_mask, input_ids_3 |
**tokenizer(prompts): the CLIP ids and mask (the second tower's ids are derived from the mask) and the T5 ids ((batch, 256)). Without input_ids_3, or without an attached T5, the T5 features are zeros. |
negative_input_ids, negative_input_ids_3 |
The tokenized negative prompt (neg = tokenizer("..."); negative_input_ids=neg["input_ids"], negative_input_ids_3=neg["input_ids_3"]); the empty prompt when omitted. |
num_inference_steps, guidance_scale, seed, latents, image, strength, ... |
As for BaseDiffusion.generate; defaults from the repo's generate_args (28 steps, guidance 7.0). latents is (batch, 128, 128, 16) at 1024px. |
Returns (batch, H, W, 3) uint8 images.
from_weights takes one extra argument, text_encoder_3: a hosted SD3T5EncoderModel
repo id (loaded at the same load_dtype) or a built SD3T5EncoderModel;
sd.text_encoder_3 can also be assigned later (or set to None). It lives outside the
container's weights.
StableDiffusion3Model
The container: four disconnected paths in one functional model, .transformer / .vae /
.text_encoder / .text_encoder_2.
| Inputs | Outputs |
|---|---|
sample (B, 128, 128, 16), timestep (B,), encoder_hidden_states (B, 333, 4096), pooled_projections (B, 2048) |
noise_pred (B, 128, 128, 16) |
image (B, 1024, 1024, 3), latent (B, 128, 128, 16) |
moments (B, 128, 128, 32), image (B, 1024, 1024, 3) |
token_ids (B, 77), token_ids_2 (B, 77), padding_mask (B, 77) |
prompt_embeds (B, 77, 2048), pooled_prompt_embeds (B, 2048) |
SD3Transformer2DModel
The MMDiT on its own ({"sample", "timestep", "encoder_hidden_states",
"pooled_projections"} -> {"sample"}), built from StableDiffusion3TransformerConfig
(sample_size 128, patch_size 2, num_layers 24, num_attention_heads 24 x
attention_head_dim 64, joint_attention_dim 4096, caption_projection_dim 1536,
pooled_projection_dim 2048, pos_embed_max_size 192, qk_norm,
dual_attention_layers). Its layers (StableDiffusion3PatchEmbed,
StableDiffusion3AdaLayerNorm, StableDiffusion3JointAttention,
StableDiffusion3JointTransformerBlock, StableDiffusion3GELUFeedForward) are named
with the diffusers module paths.
The joint attention runs over 4429 tokens at 1024px, so StableDiffusion3JointAttention
defaults to the "fused" attention implementation (keras.ops.dot_product_attention,
the backend's own kernel: torch's flash / memory-efficient kernels never materialize the
4429 x 4429 logits; see fused_attention) instead of
the library-wide "sdpa" math. from_weights(..., attn_implementation="sdpa") switches
it back.
SD3T5EncoderModel
The third text encoder, the encoder half of T5 v1.1 XXL (transformers T5EncoderModel on
google/t5-v1_1-xxl), as its own model in this family: {"input_ids", "attention_mask"}
((batch, 256) int32) -> {"last_hidden_state": (batch, 256, 4096)}, built from
StableDiffusion3T5EncoderConfig (vocab_size 32128, embed_dim 4096, key_value_dim
64, mlp_dim 10240, num_layers 24, num_heads 64, relative_attention_num_buckets 32,
relative_attention_max_distance 128, layer_norm_eps 1e-6; 4.7B parameters). The blocks
reuse the T5 family's attention, RMSNorm and relative position bias, and add the
gated-GELU feed-forward of T5 v1.1 (wo(gelu_tanh(wi_0(x)) * wi_1(x)),
StableDiffusion3T5GatedFeedForward), which the original T5 does not have. Loads on its own with
SD3T5EncoderModel.from_weights("zeromodels/t5-v1_1-xxl-encoder") (load_dtype,
quantization="int8" as needed); its inputs are the input_ids_3 of the SD 3 tokenizer.
Preprocessing
StableDiffusion3Tokenizer
StableDiffusion3Tokenizer(
    hf_id=None,
    tokenizer_file=None,
    tokenizer_file_3=None,
    max_seq_len=77,
    max_sequence_length=256,
)
Returns {"input_ids", "attention_mask", "input_ids_3"}; pass all three to generate.
End-to-end example
import os

os.environ["KERAS_BACKEND"] = "torch"  # or "jax" / "tensorflow"

from PIL import Image
from zeromodels.models.stable_diffusion_3 import (
    StableDiffusion3TextToImage,
    StableDiffusion3Tokenizer,
)

model = StableDiffusion3TextToImage.from_weights(
    "zeromodels/stable-diffusion-3-medium",
    text_encoder_3="zeromodels/t5-v1_1-xxl-encoder",  # omit on small machines: T5 features zeroed
)
tokenizer = StableDiffusion3Tokenizer.from_weights(
    "zeromodels/stable-diffusion-3-medium"
)

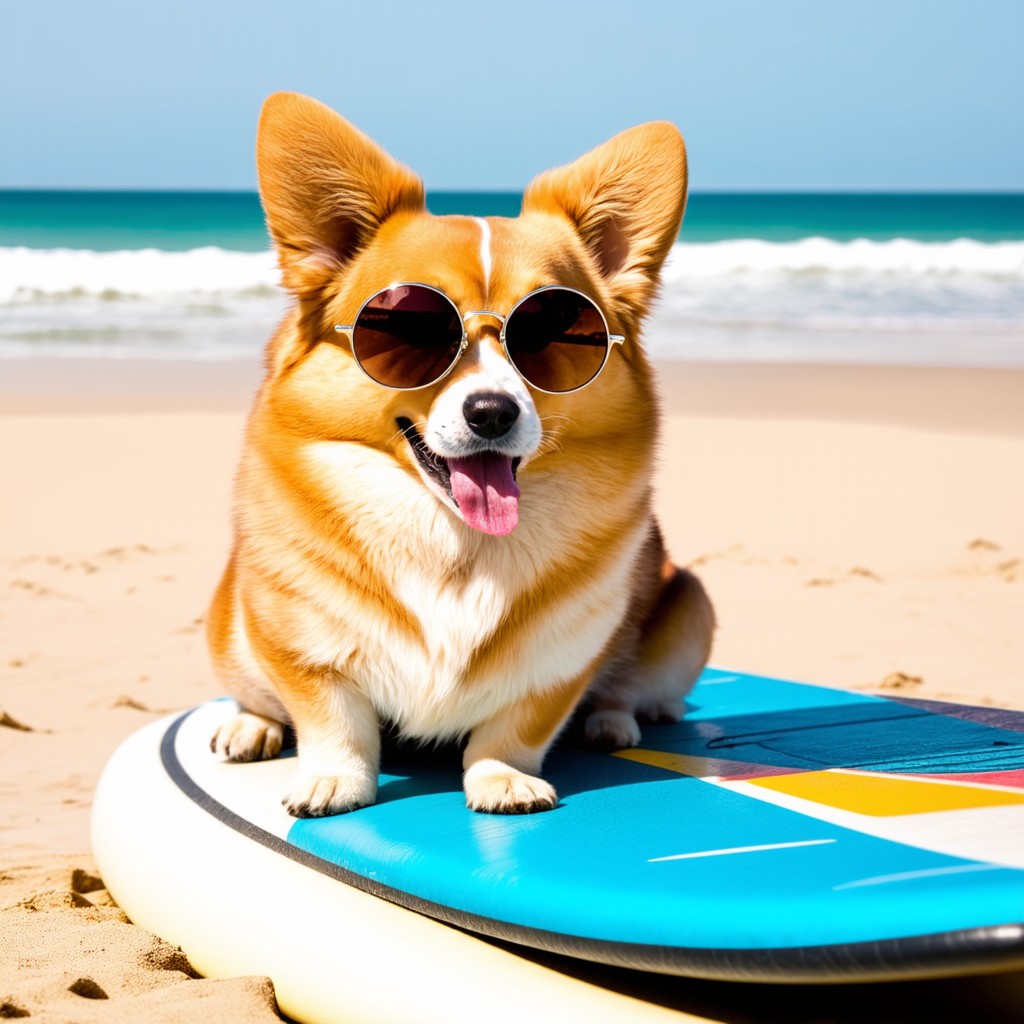
inputs = tokenizer(
    "a fluffy corgi wearing round sunglasses, sitting on a surfboard at a sunny beach, photo"
)
images = model.generate(**inputs, num_inference_steps=28, guidance_scale=7.0, seed=4)

Image.fromarray(images[0]).save("corgi.png")  # (1024, 1024, 3) uint8
The T5 encoder on the CPU
The 9.5 GB T5-XXL rarely fits next to the MMDiT on a consumer GPU. Encode the prompt
separately (an SD3T5EncoderModel in another process, or int8) and hand the ids to a
model without T5 for the CLIP part only, or attach it in full on a large machine. The
encode_prompt hook returns the conditioning dict the transformer takes, so any
precomputed T5 features can be substituted there.
Verified against diffusers
The components of stable-diffusion-3-medium were checked one by one against diffusers
0.39 / transformers 5 in float32 on the same inputs (the converted float16 weights
computed in float32):
text_encoder penultimate       max|d|=6.1e-05   (values up to 854)
text_encoder_2 penultimate     max|d|=3.1e-05
pooled (L + G, projected)      max|d|=3.8e-06
t5-v1_1-xxl encoder (256 tok)  max|d|=1.1e-04   (values up to 6.3)
mmdit velocity (t=1000)        max|d|=9.9e-06
vae decode (512px)             max|d|=6.3e-05
vae encode                     max|d|=1.4e-05
The pipeline (flow-match Euler with shift 3, classifier-free guidance with the encoded
empty prompt, the three tokenizers, batched negative prompts, the no-T5 mode) was checked
against StableDiffusion3Pipeline on a small random-weight SD 3, where the generated images
are pixel-identical on torch and jax. End to end, stable-diffusion-3-medium without the
T5 encoder (28 steps, guidance 7, the same initial latent) reproduces the diffusers
pipeline in float32 at 512px: 92.8% identical pixels, max |d| 2 / 255, PSNR 63.9 dB (the
final latent differs by at most 2.5e-2 with values up to 5.1). In float16 on the GPU the
two implementations round differently through the 28 guided steps: the pictures agree in
composition but not pixel for pixel (PSNR 26 dB at 1024px, 29 dB at 768px, float16 MMDiT
on both sides), the usual float16 sampling noise.
Data Format
Both channels_last and channels_first are supported; generate always returns
(batch, H, W, 3) uint8.
Memory and speed
The container is 5.8 GB in float16 (the T5 encoder adds 9.5 GB). Measured on the torch backend with the default float16 load (RTX 4060 Laptop, 8 GB), T5 features precomputed:
| Resolution | Denoising step (guided, batch 1) | VAE decode (float32) |
|---|---|---|
| 512px | peak 6.1 GB, 0.5 s/step | peak 7.6 GB, 4 s |
| 768px | peak 6.4 GB, 0.8 s/step | peak 9.5 GB |
| 1024px | peak 6.9 GB, 1.0 s/step | peak 12.4 GB |
The MMDiT itself fits an 8 GB GPU at the native 1024px thanks to the fused attention
kernel (the "sdpa" math needs 3.8 GB per block for the 4429 x 4429 float32 logits and
runs out of memory). The VAE decoder is the SDXL one (16 latent channels aside) and Keras'
functional executor keeps its feature maps alive, see the
SDXL notes: on 8 GB, denoise on the GPU
(output_type="latent") and decode on the CPU (75 to 90 s at 1024px). The T5-XXL encoder
encodes a prompt and its negative on the CPU in about 10 to 25 s (float32 compute over
the float16 weights); a 24 GB GPU holds everything. On JAX and TensorFlow the denoiser
step is compiled once per run.
Loading Fine-tuned Weights
Any repo laid out like the hosted ones (zm_config.json declaring
StableDiffusion3Model, the weights, the two tokenizer files) loads with
from_weights("<org>/<repo>"). The hf: prefix raises for diffusion models: convert a
diffusers-format SD 3 checkpoint once with
zeromodels/models/stable_diffusion_3/convert_stable_diffusion_3_diffusers_to_keras.py
(transfer_stable_diffusion_3(repo); transfer_t5_encoder(repo) for the T5 tower) and host the
result.