Stable Diffusion 3.5
zm_config.json + the float16 weights +
tokenizer.json / tokenizer_3.json). Load with
from_weights("zeromodels/<variant>").
Stable Diffusion 3.5, ported to pure Keras 3: the Stable Diffusion 3
architecture, retrained and scaled. It reuses the SD 3 family end to end
(StableDiffusion3_5Model is StableDiffusion3Model, StableDiffusion3_5TextToImage is
StableDiffusion3TextToImage, each with the SD 3.5 configuration), so everything on that
page applies: the MMDiT, the three text encoders with the separately hosted T5-XXL, the
16-channel VAE, the flow-match sampler, one tokenizer call. What changes is the config:
- QK normalization: every attention block RMS-normalizes its queries and keys per head
(
qk_norm="rms_norm"), the training stabilizer of SD 3.5. - Large (8B): 38 blocks of 38 heads (2432-d tokens), 28 steps at guidance 3.5.
- Large Turbo: the large model distilled with Adversarial Diffusion Distillation to 4
steps without guidance (
guidance_scale=0.0). - Medium (2.5B, MMDiT-X): 24 blocks of 24 heads with dual attention in blocks 0 to 12 (a second, latent-only attention with its own modulation next to the joint one) and a 384x384 position grid (up to 2 MP); 40 steps at guidance 4.5.
The weights are converted once, offline, and hosted: on-the-fly hf: conversion is
deliberately not supported for diffusion models. The upstream repos are gated behind
the Stability AI Community License.
Links:
- Paper: Scaling Rectified Flow Transformers for High-Resolution Image Synthesis (arXiv:2403.03206)
- Reference implementation: diffusers
StableDiffusion3Pipeline - License: Stability AI Community License
See also stable_diffusion_3.md.
Variants
Each repo is one container: MMDiT + VAE (84M) + CLIP ViT-L/14 (123M) + OpenCLIP
ViT-bigG/14 (695M); the T5-XXL encoder (zeromodels/t5-v1_1-xxl-encoder, the SD 3
family's SD3T5EncoderModel, 9.5 GB) is shared and optional.
| Variant | Hub | MMDiT | Sampler | Size |
|---|---|---|---|---|
stable-diffusion-3.5-large |
zeromodels/stable-diffusion-3.5-large |
38 x 38 heads, 8B | flow-match Euler (shift 3), 28 steps, guidance 3.5 | 17.8 GB float16 |
stable-diffusion-3.5-large-turbo |
zeromodels/stable-diffusion-3.5-large-turbo |
38 x 38 heads, 8B | 4 steps, no guidance | 17.8 GB float16 |
stable-diffusion-3.5-medium |
zeromodels/stable-diffusion-3.5-medium |
24 x 24 heads + dual attention, 2.5B | flow-match Euler (shift 3), 40 steps, guidance 4.5 | 6.8 GB float16 |
API
StableDiffusion3_5Config (model_type "stable_diffusion_3_5") is
StableDiffusion3Config over StableDiffusion3_5TransformerConfig (the SD 3.5 large
defaults: num_layers 38, num_attention_heads 38, caption_projection_dim 2432,
qk_norm="rms_norm"; medium's repo carries dual_attention_layers=(0, ..., 12) and
pos_embed_max_size=384). StableDiffusion3_5TextToImage.generate and
StableDiffusion3_5Tokenizer are the SD 3 ones; see
Stable Diffusion 3.
End-to-end example
import os

os.environ["KERAS_BACKEND"] = "torch"  # or "jax" / "tensorflow"

from PIL import Image
from zeromodels.models.stable_diffusion_3_5 import (
    StableDiffusion3_5TextToImage,
    StableDiffusion3_5Tokenizer,
)

model = StableDiffusion3_5TextToImage.from_weights(
    "zeromodels/stable-diffusion-3.5-medium",
    text_encoder_3="zeromodels/t5-v1_1-xxl-encoder",  # optional
)
tokenizer = StableDiffusion3_5Tokenizer.from_weights(
    "zeromodels/stable-diffusion-3.5-medium"
)

inputs = tokenizer(
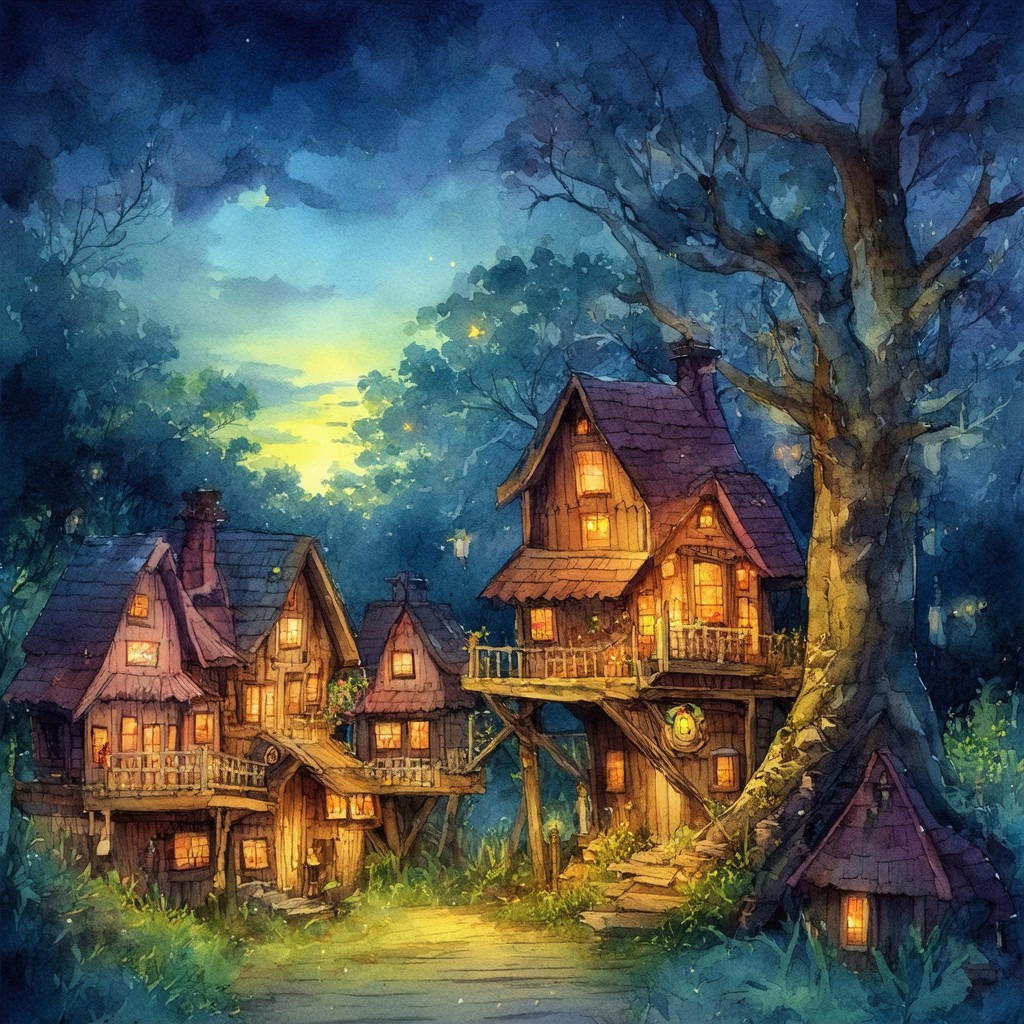
    "a whimsical treehouse village at twilight, lanterns glowing, watercolor illustration"
)
images = model.generate(**inputs, num_inference_steps=40, guidance_scale=4.5, seed=5)

Image.fromarray(images[0]).save("treehouse.png")  # (1024, 1024, 3) uint8
Large Turbo
model = StableDiffusion3_5TextToImage.from_weights(
    "zeromodels/stable-diffusion-3.5-large-turbo"
)
images = model.generate(
    **tokenizer("a red panda reading a book")
)  # 4 steps, guidance 0 (the repo defaults)
Verified against diffusers
The components of stable-diffusion-3.5-medium (the MMDiT-X with dual attention and RMS
qk norms) were checked against diffusers 0.39 in float32 on the same inputs (the converted
float16 weights computed in float32): MMDiT velocity max|d| 1.6e-5 (values up to 5.2), the
text encoders and the VAE as for SD 3.
The SD 3.5 block variants (dual attention, qk_norm) are also covered by the small
random-weight pipeline test, pixel-identical to StableDiffusion3Pipeline on torch and
jax, and by the SD 3 float32 end-to-end check (92.8% identical pixels, PSNR 63.9 dB at
512px), which the two families share down to the sampler. The picture above is the
1024px float16 output of stable-diffusion-3.5-medium with the T5 encoder.
Memory and speed
The medium container is 6.8 GB in float16, the large ones 17.8 GB (a 24 GB GPU); the T5-XXL encoder adds 9.5 GB. See Stable Diffusion 3: the medium MMDiT-X at 1024px peaks at 7.5 GB during the guided denoising step on the torch backend (fused attention, float16), which an 8 GB GPU runs with the VAE decode on the CPU.
Loading Fine-tuned Weights
Any repo laid out like the hosted ones (zm_config.json declaring
StableDiffusion3_5Model, the weights, the two tokenizer files) loads with
from_weights("<org>/<repo>"). Convert a diffusers-format checkpoint once with
zeromodels/models/stable_diffusion_3_5/convert_stable_diffusion_3_5_diffusers_to_keras.py
and host the result.